Mac app
Available
Local dictation, meeting capture, transcript library and export.
Where audio goes, where notes live, and what remains to be built.
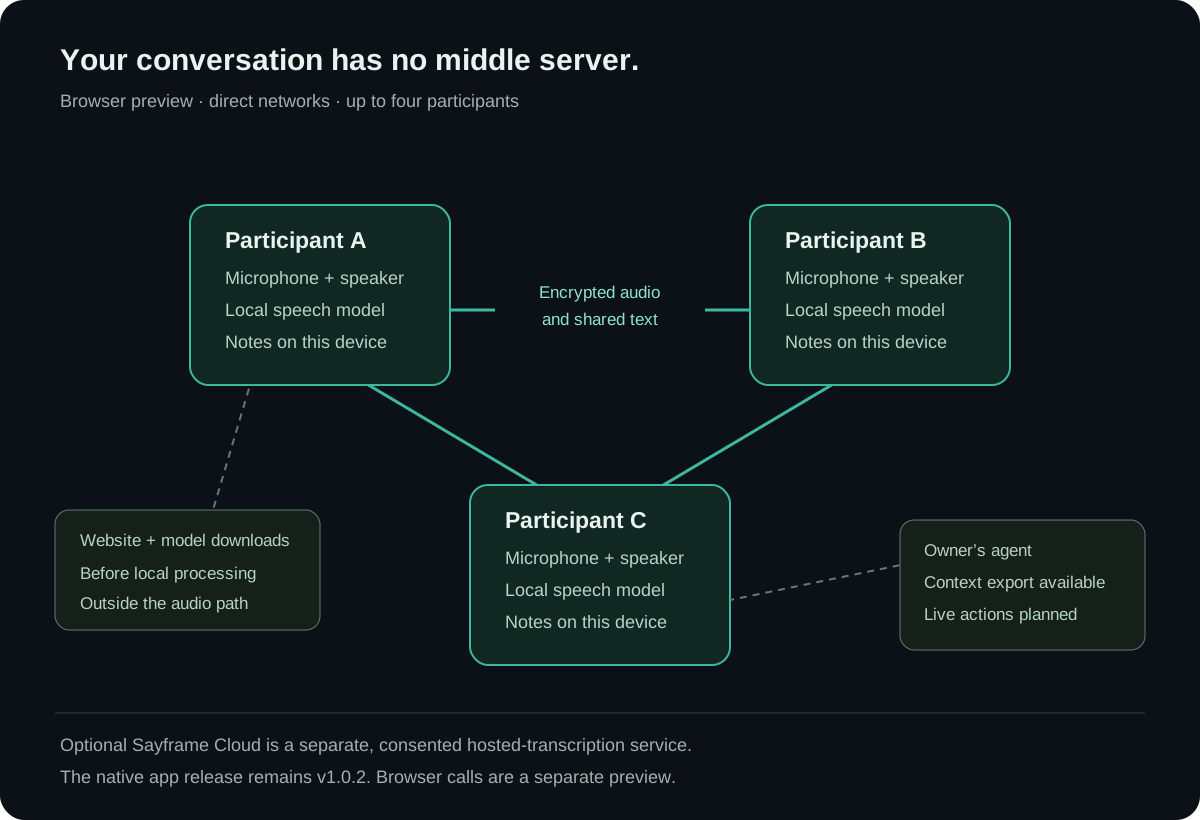
Each participant connects to every other participant using WebRTC’s encrypted media and data channels. The host introduces peers but does not forward their audio. Invite and answer codes travel through a channel you choose.
This preview uses no STUN or TURN service. Direct connectivity is required, so some networks cannot connect. It does not promise universal internet reachability.
Opt-in transcription downloads an English speech model, then runs it locally. Only the resulting text is shared directly with the people in the call. Each person keeps an in-memory copy and can export it.
The model host receives download requests, not your audio. Sayframe Cloud is a separate hosted option: it reads audio only when you submit audio to that service.
Available
Local dictation, meeting capture, transcript library and export.
Browser preview
Up to four browser participants, direct encrypted audio, shared notes and opt-in local transcription.
Optional hosted service
Separately chosen hosted transcription; this service reads the audio you submit.
Native foundation
Identity, pairing and a LAN demonstration exist. Production native calls still require transport and device acceptance.
Conversation context can be exported now. Live connections and permission-scoped automatic actions are planned.